Free
Rendered by this Skill
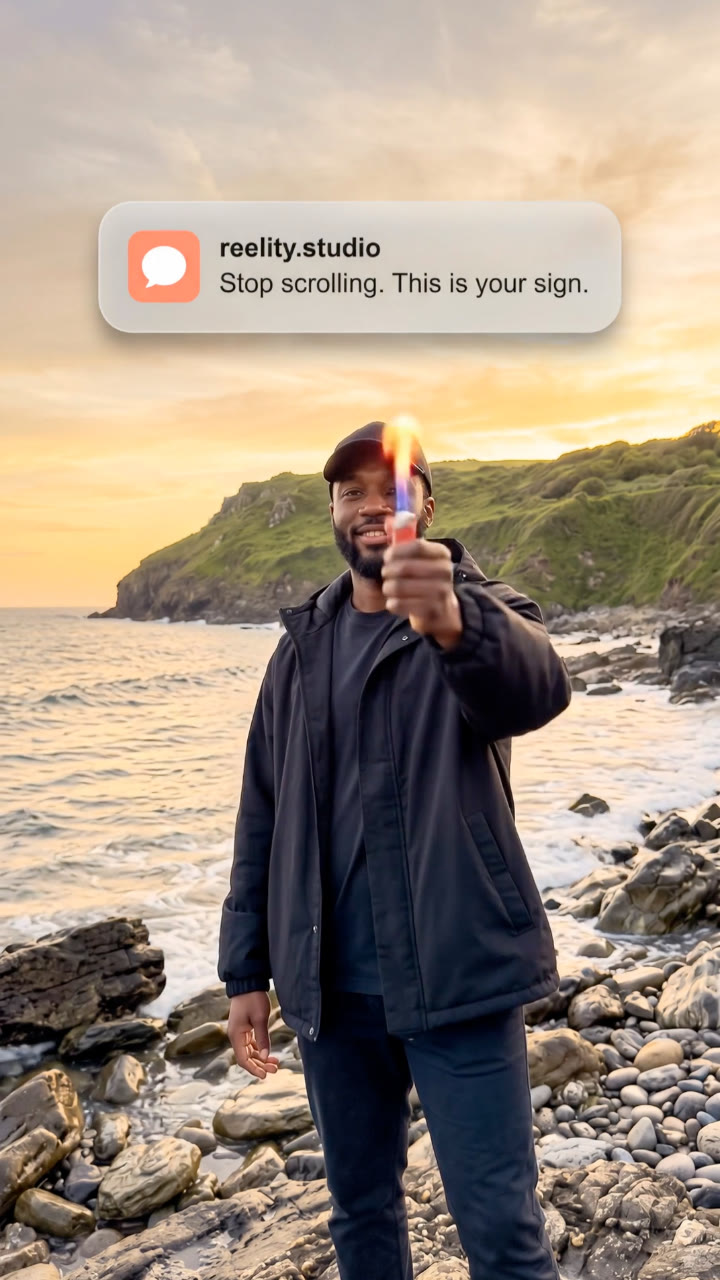
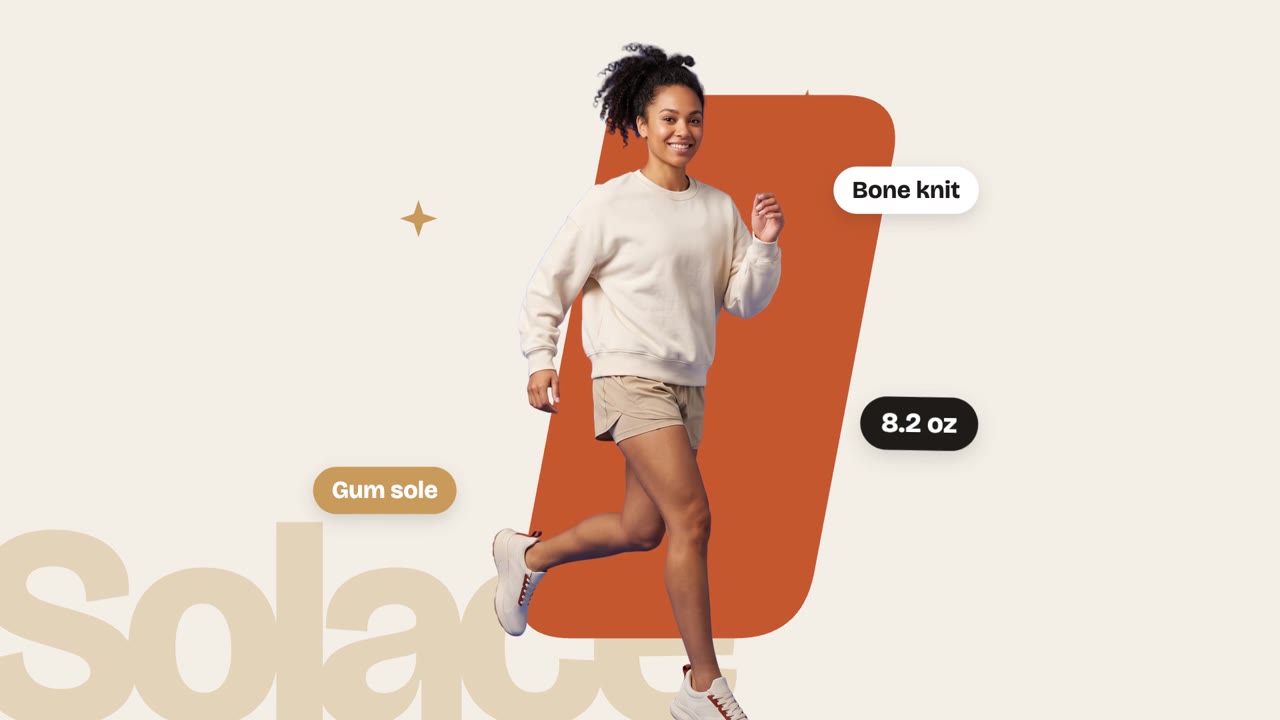
Word-by-word captions that ride on top of your video, plus one big word set behind your subject at the peak moment.
Free Free with an account
Paste this into your agent. It connects the CLI if needed, then installs the Skill.
A free Skill that teaches your agent how to caption HyperFrames videos. Every spoken phrase is dropped, put on a clean lower-third rail or, rarely, promoted to one big word placed behind the subject. Captions are an overlay on the full frame, never a reserved band, so your layout stays centred.
Updated Nov 2, 2026
/captions-overlay Add captions to this 12-second runner clip: rail captions for the voice-over, and make "soft" the one embed, set behind the runner.
Good captions are mostly invisible and sometimes spectacular. Captions Overlay gives your agent one simple model for every phrase: drop the filler, put ordinary words on a clean word-by-word rail at the bottom, and save the big moment for one word composited behind your subject. It also fixes the most common layout mistake: shifting everything up to make room for captions.
This Skill is part of the HyperFrames repository. Made by HeyGen and the HyperFrames contributors (heygen-com/hyperframes) and shared under the Apache License 2.0. The download is the Skill's instructions; HyperFrames itself runs from npm.
No reviews yet. Install the Skill and be the first to rate it.
It works from word timings you already have, such as a transcript with timestamps from your voice-over tool. The Skill decides how each phrase is shown.
Because a reserved band leaves a dead strip in every frame. The caption line is small and drawn over the picture, so the composition keeps its full frame.
It is an open-source Skill by HeyGen and the HyperFrames contributors. We list it as it is, with a sample made by running it on one of our house brands, Halden Solace.